This analysis compares Agentic RAG with Traditional RAG: Five Differences That Matter, focusing on the decision each option supports, the evidence behind it and the trade-offs.
Read the evidence below as a decision trail: what changed, why it matters, which trade-offs shaped the result, and where the conclusion still depends on context.
"Agentic RAG" is the most commonly misunderstood word in the 2025-2026 RAG community - most people think it is "RAG with agent packaging", but Microsoft Lesson 5 defines it as something completely different:Let LLM have its own reasoning process, automatically rewrite failed queries, change retrieval methods, call different tools, and iterate within configured boundaries until evidence is sufficient or a limit is reached. This article dismantles Lesson 05 and gives 5 key differences compared to traditional RAG, as well as the most easily overlooked issue: when not to use Agentic RAG.
Why this lesson is worth a second look for RAG veterans
If you’ve done a few RAG projects, you might think “Agentic RAG” sounds like a marketing buzzword. But the definition given by Microsoft is surprisingly precise:Traditional RAG is "retrieval-then-read", Agentic RAG is "retrieval ↔ reasoning, iterate according to evidence and stopping conditions". The difference is not whether to add agent or not, butwho owns the reasoning process. In traditional RAG, the developer pre-designs the chain-of-thought and the model follows it; in Agentic RAG, the model decides what to do next.
The reason why this reframing is important: When you do RAG evaluation, the questions you should ask change from "Is my chunk strategy correct?" "Is the embedding model accurate?" to "Will my agent rewrite the query and try again after getting a bad retrieval?" The latter is Agentic RAG’s real value point and its most underestimated ability.
Traditional RAG vs Agentic RAG — 5 Key Differences
| Dimensions | Traditional RAG | Agentic RAG |
|---|---|---|
| reasoning ownership | Developers pre-design the chain | The model decides its own next step |
| Query failure handling | Follow predefined handling, which can include retries or fallbacks | rewrite query, change tool, change retrieval method and try again |
| Multiple retrieval methods | The developer defines the retrieval path | Dynamically mix vector search + SQL + Bing + own API |
| Cross-step memory | State and memory depend on the pipeline design | state + memory across steps to avoid repeated attempts |
| Stop condition | Stop after running the preset chain | Assess evidence within iteration, token and time limits, with human fallback conditions |
What the 5 dimensions have in common:From "people determine the process, model execution" to "model determines the process, people determine the boundaries". Multiple model and tool calls add tokens and latency. Whether they help with malformed queries, missing information or cross-source verification requires task-specific evaluation.
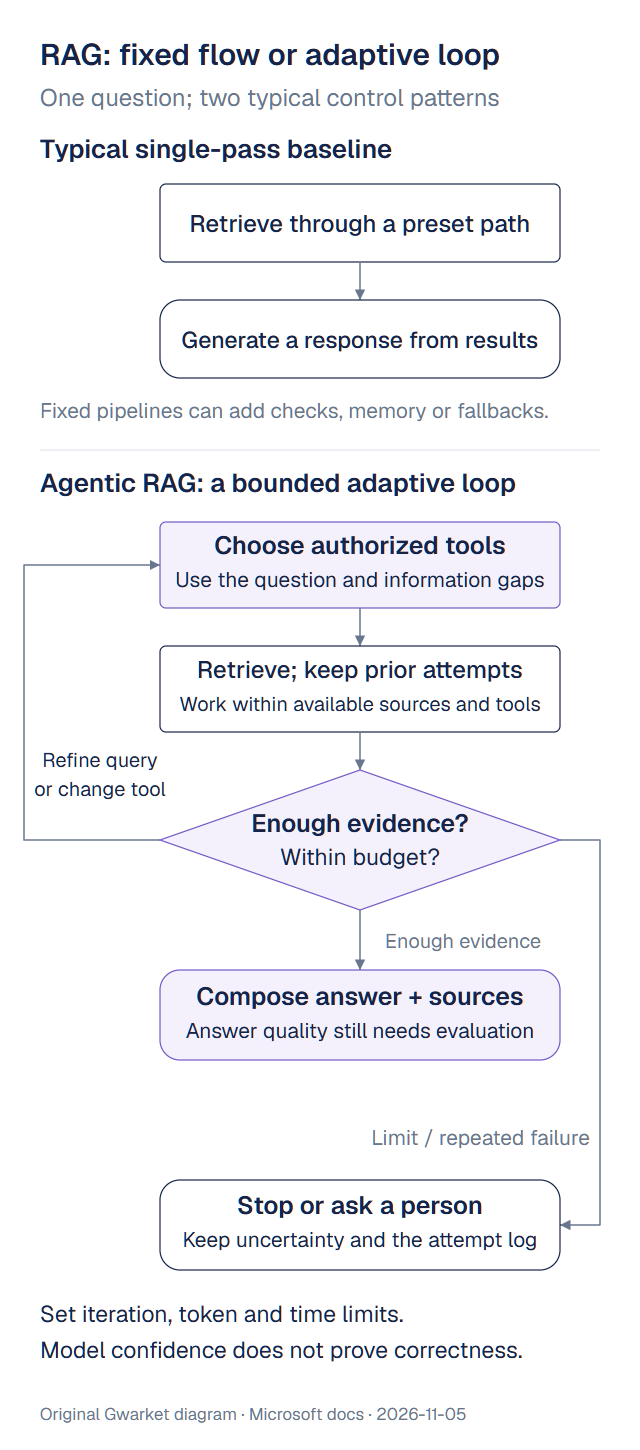
Core loop: maker-checker mode
Agentic RAG operates in a 5-step cycle:
- Initial Call:User prompt to enter LLM
- Tool Invocation: LLM found that there is a lack of information/the instructions are ambiguous, and tool (vector DB query, SQL call, API) was selected.
- Assessment & Refinement: LLM looks at the returned data and decides whether it is enough; if it is not enough, rewrite query / change tool / change method
- Repeat Until Satisfied: Retry within iteration, token and time limits; answer when evidence is sufficient, or stop or seek human help at a limit or after repeated failure
- Memory & State: Try and follow the results before recording the entire process to avoid going around in circles in the same place
Design highlights of this architecture:No complex orchestration framework required. Microsoft's original text directly says "a relatively simple loop of LLM call → tool use → LLM call →... can yield sophisticated and well-grounded outputs". When most teams see Agentic RAG, they think of the complex structure of LangChain agent. In fact, the core logic is lighter than imagined - the point isLet LLM have the authority to "decide the next step", rather than "designing a complex state machine".
Practical example (product launch strategy): The model decides on its own whether (1) Bing market trend report → (2) Azure AI Search compares opponent information → (3) Azure SQL checks internal sales history → (4) Synthetic strategy → (5) Self-evaluate whether there is any gap, and return to step 1 if so. Every step is not preset by humans, but determined by models based on current quality.
Self-Correction 3 types of failure handling
The real stress test of Agentic RAG is “what happens when it fails”. Microsoft lists 3 mechanisms:
1. Iterate and Re-Query
When you get irrelevant document or malformed query results, do not reply with low-quality answers, rewrite the strategy and try again. Specifically include: rewrite database query, change to different search methods, change to alternative dataset. This depends on the model's ability to assess results and choose tools. Model size alone does not establish suitability; evaluate retrieval quality and tool selection on the actual task.
2. Diagnostic Tools
The system can call additional functions to debug itself - such as checking traces and verifying the correctness of data. Microsoft specifically mentioned Azure AI Tracing is important for observability. The second layer of observability - Agentic RAG, which corresponds to Part 4 of "Three-tier Trust Architecture", has more steps and observability is much more important than traditional RAG. Without trace, you have no idea at which step in the 4-step cycle the model made an error and cannot be corrected.
3. Fallback to Human Oversight
For high-stakes or repeated failure scenarios, the model should be marked with uncertainty and require human intervention. This is easily overlooked - many Agentic RAG designs only have "automatic retry" and no clear trigger of "retry N times and then escalate". Without stopping conditions, the system can repeat attempts and consume its budget. Set iteration, token and time limits, then stop or seek human help where needed.Escalation policy is a necessary design of Agentic RAG, not optional。
Boundaries of Agentic RAG — not AGI
Microsoft specifically clarified that Agentic RAG is not “fully autonomous AI”:
- Domain-Specific Autonomy: Autonomous within user-defined target and known domain, cannot cross boundaries
- Infrastructure-Dependent: The ability is tied to the tool/data integrated by the developer, and it is impossible to invent new tools by oneself.
- Respect for Guardrails: Ethical guidelines / compliance / business policy always take precedence, autonomy cannot be bypassed
These 3 boundaries are very important -The "intelligence" of Agentic RAG is "flexible combination in the toolbox you provide", not "making something out of nothing". The set of tools you provide during implementation is the ceiling of the agent's capabilities. If the tool is not complete enough, no matter how smart the agent is, it will not go beyond it. Therefore, the real design work of Agentic RAG is not only in the agent prompt; it also includes tool inventory design - which tools should exist, how the tools complement each other, and whether there is a fallback tool.
Three optimal scenarios
3 use cases provided by Microsoft:
- Correctness-First Environments: Compliance inspection, regulatory analysis, legal research - accept multiple rounds of LLM calls for thoroughly vetted answers
- Complex Database Interactions: Structured data and queries often fail or need to be adjusted - Agentic RAG automatically refines SQL until it aligns with user intent
- Extended Workflows: Long session, new information continues to emerge - the system continues to integrate, and evolves with the problem space strategy
What the 3 scenarios have in common:Low tolerance for "answer quality" and high tolerance for "time/token cost". If your scenario is the other way around (fast, cheap, a single retrieval already meets the task requirements), traditional RAG is more suitable.
My Observations — When Not to Use Agentic RAG
Microsoft gave us applicable scenarios, but didn’t say anything about the negatives. 3 I would recommendNo need Agentic RAG scenario:
1. High-frequency, low-stakes Q&A (such as customer service FAQ)
For a question such as "What are your business hours?", start with traditional RAG, suitable chunking and a cached response if one retrieval can answer it. Agentic RAG does not require a fixed four-step cycle for every question. Compare actual answer quality, latency and request cost rather than treating a 5–10× multiplier as a general rule. Official trade-offs and evaluation
2. Retrieval source single, stable structure
Agentic RAG adds value by adapting queries and retrieval methods. With one stable source and questions that a single retrieval can resolve, traditional RAG is usually the better starting point. A single source can still require query decomposition or iterative clarification, so source count alone does not establish whether adaptive retrieval has value.
3. No observability / escalation design time
Agentic RAG is a black box because it has many steps, is difficult to debug, and has no trace. If your team is not ready to use tools such as OpenTelemetry + Azure AI Tracing, don't rush to use Agentic RAG - you don't know where bugs are at, users have to wait longer, and costs are out of control. Suggested order:First improve the observability and evaluation of traditional RAG, and then upgrade to Agentic RAG. The infrastructure is not in place and Agentic RAG is over-engineering.
Agentic RAG's place within gwarket's existing RAG family
gwarket’s previous RAG series discussed chunking strategy, Hybrid Search, evaluation methods, and practical decision-making frameworks—those are the optimization main axes of traditional RAG. Agentic RAG isanother axis: When your traditional RAG has been optimized to the bottleneck and continues to adjust chunks and embeddings with diminishing returns, consider moving the inference ownership from you to the model.
Judgment timing: use task evaluation to identify failure causes, then ask whether dynamic queries, source selection or cross-source reasoning can help. Fix underlying chunking, embedding or data-quality problems first. Neither 80% nor 60% accuracy is a universal upgrade threshold. Compare answer quality, tool calls, latency and cost against the existing baseline. Official evaluation dimensions
Practical questions and boundaries
What is the difference between Agentic RAG and "multi-agent + RAG"?
Not the same thing. Multi-agent + RAG is "multiple agents retrieve individually, then collaborate and integrate" - YesArchitectureSelect. Agentic RAG is "a single agent has retrieval reasoning ownership" - Yesreasoning modeSelect. The two can be combined: each agent in the multi-agent system uses Agentic RAG mode. It can also be separated: a single agent can also run Agentic RAG, and multiple agents can also run traditional RAG (each agent follows a scheduled chain).
How much higher is the cost of Agentic RAG than traditional RAG?
There is no fixed multiplier that applies to every system. Add all model reasoning, final-generation and retrieval-tool charges per request, using the chosen model, token usage, service prices and actual iteration count. Four workflow labels do not imply exactly four billable calls. Establish a traditional RAG baseline, then compare the quality gain against extra latency and cost. Official cost-per-request guidance
Is it possible to do Agentic RAG without Azure stack?
Yes. Agentic RAG is a paradigm, not a platform - the core is "LLM has reasoning ownership + dynamic tool selection + cross-step memory". A tool-calling model can serve as the core, but still needs a runtime, data tools, stopping conditions and evaluation of its task performance. Vector DB optional Qdrant / Pinecone / Weaviate / Chroma / pgvector. Tracing optional Langfuse / Arize Phoenix. The Microsoft version is bundled with Azure AI Search + Azure SQL + Azure AI Tracing for integration convenience and is not a necessary condition.
Original source: Microsoft AI Agents for Beginners — Lesson 5 Agentic RAG
There are 6 articles in this series: (1) Complete catalog of 18 lessons (2) 5 design options (3) Context Engineering Depth (4) Trust three-tier architecture (5) Browser-Use + MCP / A2A / NLWeb (6) Agentic RAG (this article)
What to take away
The article's value is in the evidence and trade-offs behind agentic RAG vs. Traditional RAG: Five Differences That Matter, not in treating the conclusion as universal.
Sources and verification date: This diagram and the necessary qualifications use Microsoft Lesson 5 (revision 719e2e08) and the Azure Architecture Center (updated June 30, 2026). Verified November 5, 2026.